Article: Tuesday 13 October
Many companies use targeting algorithms to decide who receives a discount, a coupon or an advertisement. That precision can be profitable, but it also creates privacy risks, because targeting decisions are based on what firms infer about individual customers.
Recent research by Dr Gilian Ponte of Rotterdam School of Management, Erasmus University (RSM), together with co-authors Dr Tom Boot and Prof. Jaap Wieringa of the University of Groningen, and Prof. Thomas Reutterer of Vienna University of Economics and Business, shows that firms do not have to choose between using targeting algorithms or protecting privacy.
Their paper, Where Should Firms Implement Differential Privacy in Targeting? Implications for Profitability, published in the Journal of Marketing Research, provides a practical framework for business professionals and policymakers to weigh privacy protection against profitability and to estimate the cost of that choice in advance.
Targeting is one example of algorithms making decisions that affect people. To make those decisions, algorithms divide people into categories, such as high-risk patients, promising mortgage applicants, or likely buyers. These labels are useful, but the decisions built on them shape how people are subsequently treated. How much may an algorithm infer about someone and how far should that inference steer a decision?
“Targeting algorithms can be profitable because they make decisions more precise, but that precision also creates privacy risks for individual customers. The goal of my work is to make that trade-off visible, measurable, and manageable,” says Ponte, Assistant Professor of Marketing.
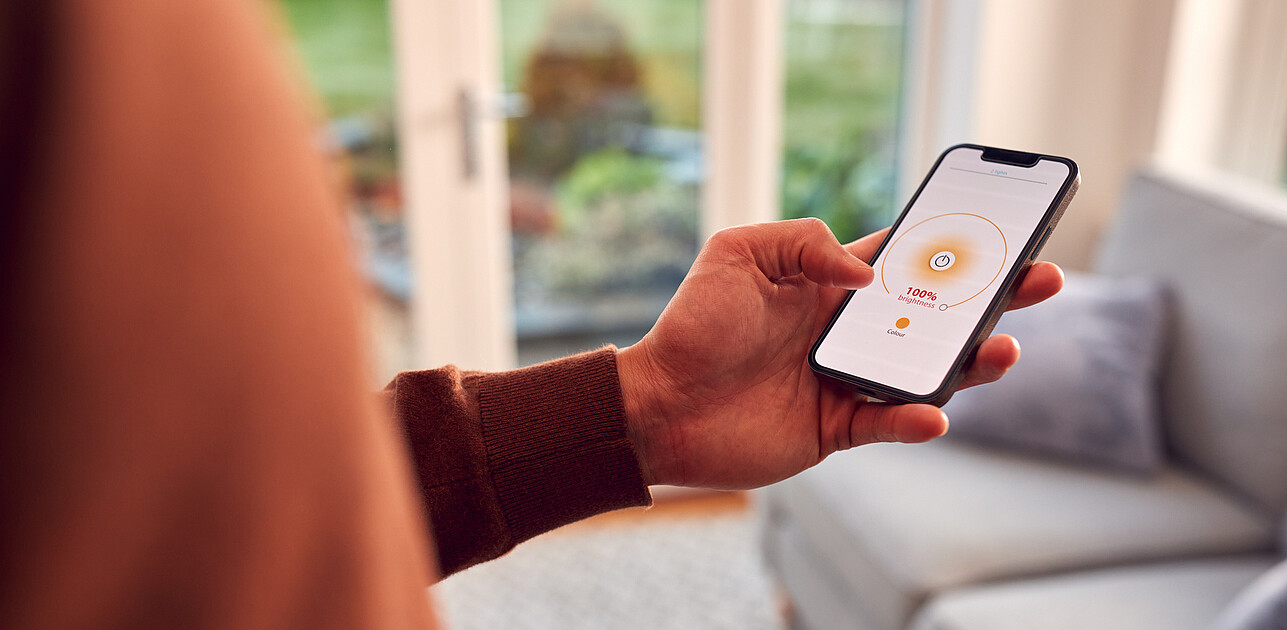
For Ponte, this trade-off shows that the AI privacy debate shouldn’t be reduced to whether to use algorithmic targeting at all, or whether personal data is sensitive or not: “Privacy in algorithmic targeting should not be treated as a simple yes-or-no decision. My research shows that firms and policymakers can treat privacy as a dimmer: they can decide how much protection is needed and understand the profitability consequences of that choice.”
The mathematical tool behind this so-called dimmer is differential privacy, which allows firms to measure and limit privacy risk by adding controlled randomness to a decision, making it harder to trace back to a person.
Think of it with a simple example. Suppose an algorithm predicts that a customer wants to buy a product. Instead of always sending an ad based on that prediction, the company rolls a die and sends it only if it lands on six. Chance now plays a big part in the decision, so receiving the ad says much less about that specific person. If the ad is sent on five out of six rolls, chance plays a smaller role, and the ad reveals more. By dialling this randomness up or down, a firm controls how much it protects its customers’ privacy.
Turning this dimmer up also means that the algorithm's predictions play a smaller role in who is targeted. What does this mean for profitability? To answer this question, Ponte and his co-authors examined where firms should add the randomness and what this means for their profits.
The researchers developed two strategies that add randomness at different stages. The first adds it during the model training when the algorithm learns to predict customer behaviour, so the data is blurred from the start. The second adds it when the firm decides whom to target. Here, the algorithm's predictions stay sharp for longer, and the randomness comes in only at the very last step.
They tested both strategies in two ways:
Both strategies remained profitable even under strong privacy protection, so firms don't have to give up all their targeting value. But one worked much better. Adding randomness at the decision stage delivered on average five times more profit than adding it during model training, for the same level of privacy protection. That’s because adding it early blurs the information before the firm has used it, while adding it late keeps predictions sharp longer and introduces uncertainty only at the final step.
To make these findings usable beyond the dataset studied, Ponte and his co-authors worked out how much profit a firm can expect at a given level of privacy protection. They also introduced a simple measure they call the privacy elasticity of targeting profits, which shows how much profit changes for every one-per cent increase in privacy protection. Together, these tools let business professionals and policymakers estimate the cost of a chosen level of privacy protection before targeting a single customer.
The findings turn privacy protection from a vague commitment into a design choice with an estimable cost. A firm can:
To help professionals experiment with these strategies, Ponte released a Python package with worked examples.
This research offers concrete guidance on implementing differential privacy in targeting. By making the trade-off measurable, it turns an abstract debate into practical questions:
The dimmer does not need to be set the same way everywhere. More risk might be acceptable in retail advertising than in healthcare, insurance or mortgage applications, where the stakes for individuals are much higher. In that sense, the research's contribution is not only technical. It helps build a language for deciding where to set the dimmer and how much power data-driven systems should have in shaping the reality people live in.

Read the full article here: Where Should Firms Implement Differential Privacy in Targeting? Implications for Profitability
Science Communication and Media Officer
Rotterdam School of Management, Erasmus University (RSM) is one of Europe’s top-ranked business schools. RSM provides ground-breaking research and education furthering excellence in all aspects of management and is based in the international port city of Rotterdam – a vital nexus of business, logistics and trade. RSM’s primary focus is on developing business leaders with international careers who can become a force for positive change by carrying their innovative mindset into a sustainable future. Our first-class range of bachelor, master, MBA, PhD and executive programmes encourage them to become to become critical, creative, caring and collaborative thinkers and doers.